A low chance of a claim can still create serious financial exposure when the loss would be large. That gap matters when we protect household finances from uncertain events. Insurance Probability and Loss Severity helps us weigh how often claims may happen against the cost they may bring.
Exposure means the units of risk observed over a defined time, such as one insured home-year or 100 house-years. We can use claim data to estimate expected costs, build models, and make better risk decisions. An average helps, but it cannot describe every possible loss or show how severe the worst outcomes might be.
We will connect claim records with cost estimates, modeling choices, coverage terms, and insurer decisions. The aim is practical: understand what a number says before using it to make a choice. Readers can use the two measures to see both how often losses happen and how costly they may be.
Key Takeaways
- Claim frequency tracks how often claims occur over stated exposure.
- Claim severity describes the cost when a claim occurs.
- Frequency and severity together estimate expected claim costs.
- Policy terms can change how much an insurer pays.
- Model results depend on data, assumptions, and portfolio changes.
- Large rare claims can matter even when the average is modest.
What Are Insurance Probability and Loss Severity?
Claim frequency tells us how often claims are expected over a stated exposure, while claim severity tells us how costly a claim is once it occurs. Together, these measures describe different parts of insurance risk.
Frequency is an expected claim count or rate over exposure, not simply the chance of at least one claim. Severity is the amount paid or incurred for a claim, based on a clear loss-cost definition.
Claim frequency describes how often losses occur
Claim frequency can refer to the expected number of claims during a period. It can also be reported as a rate, such as claims per policy-year or per house-year.
The exposure unit gives the rate meaning. One policy-year and 100 house-years describe different amounts of observed risk, so the denominator must stay clear.
Claim severity measures the cost of a loss
Loss severity focuses on a claim’s cost after a claim occurs. The amount may be paid or incurred, and the measure must say whether adjustment expenses are included.
Frequency describes how often claims arise over exposure; severity describes claim cost conditional on a claim occurring.
A frequency-severity model keeps these as two distinct components. That makes it easier to see whether a change comes from claim counts, claim costs, or both.
Always identify the time period and loss-cost measure before comparing either number.
How Is Claim Frequency Different From Claim Probability?
A rate of 5 claims per 100 exposure units is not the same statement as a 5 percent chance that each unit has a claim. The difference is count versus event.
A claim-count variable can include several claims in one exposure unit, while an event probability only asks whether one or more claims occurred. That distinction affects how we read frequency data.
Claim counts are whole-number outcomes
We can represent the number of claims as a random variable N. It takes non-negative integer values: 0, 1, 2, or more claims.
The mean claim count, E(N), adds each possible count multiplied by its probability. Its variance is E(N²) minus [E(N)]², showing how widely counts vary around the mean.
A probability of at least one claim is different. It combines the chances of one claim, two claims, and every higher count into one event measure.
Exposure makes frequency rates comparable
An exposure denominator lets us compare groups observed for different amounts of time. Policy-years and house-years are common units, but they must match the risk being measured.
Three measures answer different questions:
- Number of claims: the observed count in a defined group.
- Claims per exposure unit: a rate adjusted for exposure amount.
- Probability of one or more claims: the chance of a claim event.
For example, five claims among 100 house-years could include multiple claims at one home and none at many others. A 5 percent event chance would mean something else.
Keep the count, exposure denominator and event probability separate when reading a frequency result.
What Is the Insurance Probability and Loss Severity Formula?
Expected claim cost is expected claim frequency multiplied by expected claim severity. The frequency severity formula turns two estimates into one expected loss cost.
Expected claim cost per exposure unit equals expected claim frequency times expected claim severity. The frequency and severity estimates must use compatible exposure and loss definitions.
Calculate expected claim cost from frequency and severity
In symbols, pure premium = expected claim frequency × expected claim severity. Pure premium means expected claim cost before expenses and margins.
Frequency must use the same exposure unit as the resulting cost. Severity must also match the intended payment measure, including any stated treatment of expenses.
This calculation estimates the claim cost tied to an exposure unit. It does not add other amounts an insurer may need to cover its operations or risk.
Work through a clearly hypothetical example
Consider an explicitly hypothetical example: 0.1 expected claims per exposure unit multiplied by $5,000 per claim equals $500 expected claim cost per exposure unit.
The arithmetic is simple, but the interpretation depends on the inputs. If the frequency is annual, the severity and result must use a compatible annual exposure basis.
The $500 result is before expenses, reinsurance costs, risk margins, and profit margins. Those items can affect the customer-facing rate.
Treat this product as an expected loss measure, not as the final premium charged to a policyholder.
Which Distributions Model Claim Frequency?
A Poisson model is a natural starting point for counts when one average rate adequately describes the exposure group. Other models fit different patterns in claim data.
Model choice depends on how counts vary across exposure units and whether the exposure setup matches the model’s assumptions. A good fit should represent both typical counts and unusual counts.
Poisson models a count with a stable average rate
A Poisson distribution models non-negative claim counts with one rate parameter. It works best when a group has a stable average count and the count variation suits that assumption.
A negative binomial model can represent more variation than a Poisson model. It may fit groups where some exposure units have much higher counts than others.
Negative binomial allows more count variation
A binomial distribution describes the number of claims across a fixed number of independent exposure units with a common probability. It suits a setup where each unit has a defined claim-or-no-claim outcome.
The table compares the main use and a key limitation for each frequency distribution.
| Distribution | What it models | Useful modeling condition | Limitation to check |
|---|---|---|---|
| Poisson | Non-negative claim counts | One stable average rate | May not capture extra count variation |
| Negative binomial | Counts with added variation | Count spread exceeds Poisson fit | Needs suitable data for added variation |
| Binomial | Claims across fixed units | Independent units share a probability | Fixed-unit assumptions may not fit exposure |
We should compare observed counts with the model’s predicted spread, not just its average. A model can match the mean and still miss clusters of high counts.
Check whether the observed counts vary more than the selected model can represent before relying on its tail probabilities.
Which Distributions Model Claim Severity?
A gamma distribution is a common choice when we need a continuous model for claim amounts. Other severity models represent different shapes in losses.
We choose a distribution by checking how well its shape and tail match the claims we need to model. Claim costs often have a long right tail, with a few large amounts.
Gamma and Weibull model continuous loss amounts
The gamma distribution can describe positive, continuous claim amounts. Its mean is αθ, and its variance is αθ², where α and θ are its shape and scale parameters.
The Weibull distribution offers a flexible hazard shape. Hazard describes how the rate of an event changes over time or another measured scale.
For Weibull shape parameter α, the hazard decreases when α is below 1, stays constant at 1, and increases above 1. This flexibility can suit different claim patterns.
Pareto and lognormal capture heavier tails
Pareto and lognormal distributions can represent positively skewed losses. They are options when many claims are modest but a small number reach much higher amounts.
The Pareto distribution is positively skewed and heavy-tailed. Its tail can place substantial weight on very large losses, so the chosen form matters.
Flexible models handle mixed claim populations
A single distribution may not describe a portfolio with several kinds of claims. A mixture distribution combines component distributions using weights.
For example, one component could represent small, frequent claims, while another represents large, relatively rare claims. Such a mixture can better reflect a heterogeneous portfolio.
The four-parameter GB2 distribution can model positively or negatively skewed data. Its flexibility still requires careful comparison with actual claim patterns.
| Distribution | Characteristic | Claim pattern it can represent | Main caution |
|---|---|---|---|
| Gamma | Continuous positive amounts | Common right-skewed claim costs | Check fit in the far tail |
| Weibull | Flexible hazard shape | Decreasing, steady, or increasing hazard | Shape depends on parameter choice |
| Pareto | Positive skew and heavy tail | Rare, very large claims | Tail assumptions strongly affect estimates |
| Lognormal | Positive, right-skewed amounts | Many smaller losses with a long upper tail | Large-loss fit needs close review |
Choose the distribution by comparing its tail and shape with the portfolio’s claim data, not by model name alone.
How Do We Measure Average Severity and Variation?
Mean severity is the probability-weighted average of all possible claim amounts. It gives us one central estimate of claim cost.
A mean does not show how widely claim amounts vary or how high losses can reach. We pair it with other measures when the range of outcomes matters.
The mean summarizes expected claim cost
For a nonnegative continuous loss X with density fX, the mean is E(X) = ∫₀∞ x fX(x) dx. The probability density function assigns weight across possible amounts.
In plain terms, we multiply each possible claim amount by how likely it is, then add those weighted values. The integral performs that calculation across a continuous range.
A percentile answers a different question. The median is the point where half of claim amounts fall below it and half above it.
Variance and percentiles describe spread and tail position
Variance measures spread around the mean, while a high percentile marks a point near the top of the distribution. Neither measure replaces the average.
Moments can describe features such as a distribution’s mean and variance. A moment generating function can also characterize aspects of a distribution when it exists.
For a compact example, a gamma distribution with mean 8 and skewness 1 has variance 16. The values illustrate how distribution features can constrain one another.
An exponential distribution with median 1/3 has rate parameter 3 ln 2. This is a parameter-solving example, not a claim-cost estimate.
Pair the average with at least one measure of spread or a high percentile when large claims matter.
Why Can Rare Claims Distort Average Loss Severity?
A portfolio can have a modest average claim while still facing a meaningful chance of a very large loss. A heavy tail gives unusual losses more weight.
A few extreme claims can move the sample mean substantially, even when most claims are much smaller. The average alone can hide that change in risk.
Heavy tails put more weight on large losses
A heavy tail means that large claim amounts remain more likely than a thin-tailed model would suggest. It does not mean claims happen more often.
Claim frequency counts how many claims occur. Tail shape concerns the possible size of each claim, so these are separate features of risk.
In the stated Pareto model, the mean exists only when α is greater than 1, and the variance exists only when α is greater than 2. These conditions show how tail assumptions affect statistical summaries.
By contrast, gamma distributions have moments for every positive order. That property does not guarantee a gamma model captures the actual large-loss pattern.
Mixtures can reflect different claim types
A mixture distribution is a weighted combination of component distributions. It can represent groups with distinct patterns inside one portfolio.
One component might capture small, frequent claims, while another describes large, rare claims. The weights show how much each component contributes to the overall claim population.
Review high percentiles and tail assumptions when a few severe claims could threaten the ability to pay.
How Do Actuaries Model Total Claims Across a Portfolio?
The traditional aggregate-loss model combines the possible claim counts with the possible sizes of those claims. It estimates portfolio-wide losses for a period.
Total loss depends on a random claim count and the amount of each claim. We can write the total as S = X₁ + X₂ + … + XN.
Combine the frequency and severity distributions
Here, N is the random number of claims, and each Xᵢ is a claim amount. If N is zero, the total claim loss is zero.
The traditional loss-distribution approach fits a frequency distribution and a severity distribution separately. Convolution combines possible count outcomes with possible claim amounts to form possible portfolio totals.
In everyday terms, we consider what may happen at each claim count, then combine that count with possible sizes for its claims. The result is a distribution of aggregate losses.
A practical workflow has four steps:
- Fit the claim-count model to exposure and claim records.
- Fit the claim-size model to individual claim amounts.
- Combine the two fitted distributions through convolution.
- Examine the aggregate distribution across possible totals.
Check how assumptions affect aggregate losses
Changing the count model can alter the chance of many claims. Changing the severity model can alter the chance of a costly total.
We can compare model results under different assumptions, especially when the portfolio contains a mix of claim types or time periods. That helps show which assumptions drive the total.
The portfolio total depends on both the number of claims and how their sizes are distributed.
How Do Deductibles, Limits and Inflation Change Severity?
A $10,000 covered loss does not necessarily produce a $10,000 insurance payment. The modeled payment depends on coverage terms and the loss value at the chosen date.
A deductible shifts an initial portion of a covered loss to the insured, while a policy limit caps payment. Inflation can also raise the amount used in a severity model.
For example, a policy with a deductible applies that term before the insurer’s payment is determined. A limit then sets the maximum payment under the applicable coverage.
| Change | Effect on modeled payment | Example of the condition applied | What to check |
|---|---|---|---|
| Deductible | Insured pays initial covered amount | $1,000 deductible on a covered loss | Policy wording and deductible basis |
| Policy limit | Caps payment under coverage | $50,000 limit on covered property | Applicable limit and sublimits |
| Inflation adjustment | Raises loss value over time | Multiply by 1 plus inflation rate | Rate and valuation date |
Inflation adjustment can change a past loss amount by multiplying it by 1 plus the inflation rate. The result depends on the rate and the period applied.
Match the severity definition to the deductible, limit and valuation date being modeled.
How Do Insurers Fit Models to Claims Data?
Model fitting begins by making claim records and exposure periods comparable. We need consistent data before a model can estimate a useful pattern.
Claims and exposure records must use compatible definitions and periods for a meaningful frequency-severity analysis. Mismatched records can distort both estimates.
Prepare comparable claim and exposure records
Actuaries review how claims were counted and how exposure was measured. They also check whether the claim records include the same types of losses over time.
Four practical checks help expose common problems:
- Exposure units: confirm the amount and period match the model.
- Claim definitions: apply the same rules across the records.
- Inflation or coverage changes: account for shifts in costs or terms.
- Unusual catastrophe events: identify periods with exceptional losses.
These checks matter when a portfolio changes. A shift in the mix of homes, vehicles, or business assets can change claim patterns even if the model stays the same.
Estimate parameters and test model fit
Maximum likelihood estimation is one way to calibrate model parameters. It selects parameter values that make the observed data likely under the chosen model.
Actuaries can compare the fitted model with actual claims and test how well it describes the data. Historical analysis, statistical models, and scenario analysis offer complementary views of risk.
The Casualty Actuarial Society’s GLM monograph on insurance rating covers model building and fit assessment. GLMs can model claim frequency, severity, and pure premium.
Recheck the fit when coverage terms, exposure mix or claim patterns change.
What Do U.S. Homeowners Claim Figures Show?
In 2023, 5.3 percent of insured U.S. homes had a homeowners claim, while a separate multiple-peril measure counted 5.33 claims per 100 house-years. These figures use different measures.
The nationwide share of homes with a claim is not the same as a claims-per-exposure rate. Property damage, including theft, accounted for 97.3 percent of homeowners claims in 2023.
The multiple-peril figures below cover HO-2, HO-3, HO-5, and HE-7 policies in North Carolina. They exclude tenants’ and condominium policies, Alaska, Texas, and Puerto Rico.
| Measure | Period | Value | Unit | Scope |
|---|---|---|---|---|
| Multiple-peril frequency | 2023 | 5.33 | Claims per 100 house-years | Specified North Carolina policies |
| Multiple-peril severity | 2023 | $20,062 | Per claim | Specified North Carolina policies |
| Weighted average frequency | 2019-2023 | 5.64 | Claims per 100 house-years | Specified North Carolina policies |
| Weighted average severity | 2019-2023 | $17,059 | Per claim | Specified North Carolina policies |
The severity measure excludes loss adjustment expenses. The nationwide share of insured homes with a claim was 6.4 percent in 2020, compared with 5.3 percent in 2023.
Do not compare the nationwide claim share directly with the North Carolina multiple-peril rate as if they used the same denominator.
What Do Homeowners Fire Claims Reveal About Severity?
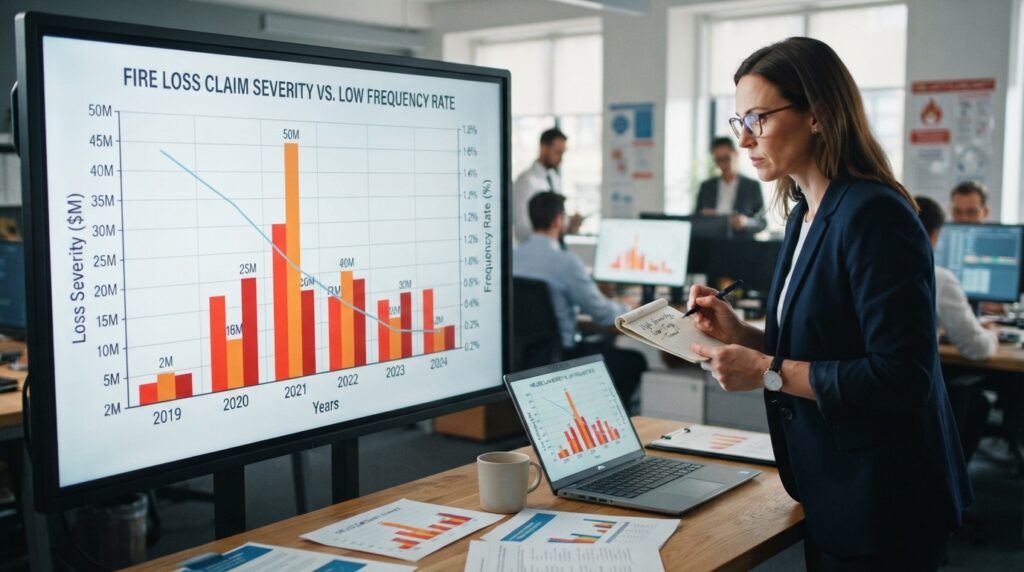
In 2024, the non-catastrophe fire measure paired 0.13 claims per 100 house-years with $173,111 in average severity. The figures show low frequency alongside high claim cost.
The 0.13 rate is claims per 100 house-years, not the probability that every home experiences a fire. It measures claim counts against exposure.
The figures cover homeowners multiple-peril policies HO-2, HO-3, HO-5, and HE-7 in North Carolina. They exclude tenants’ and condominium policies, Alaska, Texas, and Puerto Rico.
The $173,111 severity is accident-year incurred indemnity losses per claim. It excludes loss adjustment expenses and concerns non-catastrophe fire claims.
A low rate does not make the financial impact of an individual fire claim small. The two measures answer different questions about the same risk.
Read both figures together, while keeping their non-catastrophe and policy scope in view.
How Do Insurers Use Frequency and Severity Estimates?
Insurers use expected claim cost as a starting point, not as the whole amount charged to a policyholder. The estimate helps guide decisions about rates and financial needs.
Pure premium estimates expected claim cost before expenses and margins. A final rate can also account for expenses, reinsurance costs, risk margins, and profit margins.
Pricing starts with expected claim costs
Frequency and severity measures help insurers estimate expected claim costs for a group of policies. The estimates can inform pricing, but they do not set the full customer-facing rate by themselves.
Insurers also use these measures for several other purposes:
- Pricing: estimate claim costs for a policy group.
- Reserve estimates: plan for claim payments and related obligations.
- Claims operations: assess expected claim activity and workload.
- Reinsurance planning: manage exposure to large portfolio losses.
Reserves and reinsurance address different financial needs
Reserves help insurers plan for claims they expect to pay. Reinsurance is coverage an insurer buys to help manage losses that exceed its own risk appetite or capacity.
Frequency describes the expected number of claims, while severity informs the expected cost of each claim. Together, they support planning for both routine claims and large portfolio losses.
Ask which expenses and risk provisions sit outside the expected-claims estimate when comparing rate explanations.
How Can Businesses Respond to Different Loss Risks?
A business should choose a response based on both the expected frequency and the potential financial impact. The right response depends on the loss and the business’s ability to bear it.
Insurance is commonly suited to low-frequency, high-severity risks, while frequent small claims may call for controls or budgeting. Each business has different needs and resources.
Reduce or avoid preventable loss exposures
Four common risk responses give a business a practical set of choices:
- Accept or retain the risk and pay for losses if they occur.
- Prevent or reduce risk through controls and safer practices.
- Avoid the risk by ending or not starting the activity.
- Transfer risk through insurance or another agreement.
Frequent small claims may be manageable through controls or a planned budget, depending on the business. A small fender-bender pattern, for example, can prompt a review of vehicle maintenance and safe-driving practices.
That review can address a preventable cause without assuming that frequent small claims will inevitably lead to a severe one. The pattern itself is a reason to inspect work practices.
Retain or transfer the financial impact
A deductible is one form of risk retention by the policyholder. The business accepts some cost in exchange for coverage that applies under the policy’s terms.
Insurance can transfer part of a financial loss, but it does not remove the need to understand what the policy covers. A business can compare that protection with its own capacity to absorb losses.
Review recurring small claims for a controllable cause before deciding to absorb or transfer their cost.
What Are the Limits of Frequency-Severity Models?
A fitted model describes a structured estimate, not a promise that future claims will follow the same pattern. Its results depend on past data and chosen assumptions.
Historical records may not include rare catastrophe outcomes, and separate models may miss links between claim counts and claim sizes. Those limits can affect a forecast.
Historical records may miss rare events
A frequency-severity model uses separate frequency and severity distributions. A model calibrated on historical claims describes the data and assumptions used to fit it.
When a rare catastrophe did not occur during the record period, the model has little direct evidence about that event. Scenario analysis can test conditions beyond the fitted history.
Assumptions and portfolio changes can weaken a fit
Separate count and claim-size models may miss dependence between the two. For example, shared conditions could affect both how many claims occur and their average size.
Research on dependent frequency-severity modeling examines ways to model those links. A shared catastrophe can also create related claims across many policies.
Changes in coverage, exposure mix, or inflation can make old estimates less representative. The aggregate loss still depends on both claim counts and claim amounts.
Treat model outputs as decision support, not a guarantee of future claims. Revisit them when the portfolio or coverage changes.
Different scenarios can expose risks that a fitted history does not show, especially when rare losses could have a large impact.
Conclusion
Frequency and severity answer different questions, so we get a clearer view of risk by considering both. Frequency describes expected claim occurrence, while severity describes cost conditional on a claim.
Before acting on an estimate, we should check its exposure definition, loss measure, and model assumptions. A precise number can still mislead when those parts do not match the decision.
For a real portfolio, start by checking that its claim records, exposure units and coverage terms match the decision you need to make.