A portfolio can face serious disaster exposure even when no single asset looks risky, making Catastrophic Risk Insurance Modeling useful. We use it to estimate possible financial losses, not to predict the exact date or location of a disaster.
Insurers, reinsurers, banks, businesses, and public agencies can use risk estimates to make better business decisions. The results can help teams compare possible outcomes and plan for financial shocks, but they depend on the information and assumptions behind them.
We will explain how catastrophe models work, what their outputs mean, and where their limits matter. Treat model results as decision support that must be read alongside the assumptions behind them.
Key Takeaways
- Catastrophe models estimate possible losses; they do not forecast an exact disaster date or place.
- Exposure records, event assumptions, and coverage terms shape the results.
- AAL and PML describe different parts of possible loss.
- Hazard maps show local hazard, while models can estimate financial loss across a portfolio.
- Different models may produce different results because they represent risk in different ways.
- Teams should match each model output to a clear decision and retain its assumptions.
What Decisions Can Catastrophe Models Support?
An insurer can use modeled losses to decide whether a portfolio needs tighter limits or more risk transfer. Catastrophe models also help insurers, reinsurers, financial institutions, corporations, and public agencies compare possible outcomes before making commitments.
These estimates inform decisions, but they do not make decisions automatically. The same model output may matter differently to a bank, an insurer, or an agency planning emergency services.
- Assess portfolio exposure and find concentrations that may produce large losses.
- Inform underwriting by showing how modeled loss varies among risks.
- Plan reinsurance by comparing possible losses with protection already in place.
- Support capital or resilience planning by testing financial and safety needs.
Moody’s offers more than 400 catastrophe models in nearly 100 countries, reflecting the range of perils, regions, and uses. Model choice still matters: a tool built for a particular hazard or portfolio may not answer every question.
Match the model output to the decision at hand, rather than treating one metric as a complete view of risk.
A business may focus on whether one site can withstand a disruption, while a bank may study many loans at once. Public agencies can use modeled outcomes to compare planning needs across communities.
Risk modeling also gives teams a shared way to discuss possible losses, even when each group has a different role. We should define the decision first, then choose the output that speaks to it.
Which Catastrophe Perils Can Models Represent?
Catastrophe models can represent natural hazards and some human-caused events, but coverage varies by model. A hurricane model may represent wind, storm surge, and rainfall as separate but connected sources of damage.
Confirm that the peril definition matches the hazard and loss scenario we need to assess. One model may cover a specific hazard well while leaving another outside its scope.
Common natural catastrophe risk groups include:
- Hurricane and wind, including storm surge and rain linked to a storm.
- Earthquake, which can damage buildings and infrastructure through ground shaking.
- Flood, including water that reaches assets from rivers, rain, or coastal events.
- Wildfire, which can damage structures and disrupt nearby communities.
- Severe convective storm, such as damaging thunderstorms and related hazards.
Other natural perils include extratropical cyclones and winter storms. Each peril can involve connected hazards, but a model’s event definition determines which effects it represents.
Some catastrophe models also address human-caused events. Examples include terrorism, warfare, casualty events, forced displacement, and cyber breaches.
These events do not share one physical cause or one loss pattern. A cyber model, for example, will not answer the same question as a flood model.
Catastrophe modeling therefore starts with a clear view of the event we want to examine. Check that the model’s peril definition matches the hazard and loss scenario the organization needs to assess.
What Information Goes Into a Catastrophe Model?
A model cannot estimate a building’s loss reliably if its address or insured value is wrong. The information entered for analysis is called exposure, and it can describe one asset or an entire portfolio.
Missing, stale, or imprecise location data can produce misleading results. Location fields may include a street address, postal code, county, or CRESTA zone, a defined catastrophe risk area.
| Data group | Examples | Why it matters |
|---|---|---|
| Location | Address or postal code; geocoding | Places the asset in a hazard area |
| Physical characteristics | Construction; occupancy; year built | Helps describe how the asset may respond |
| Financial terms | Value; limit; deductible | Sets the insured share and retained loss |
Geocoding turns a written address into map coordinates. A postal code may cover a wide area, so it can place a property less precisely than a verified street address.
Physical details also affect risk modeling. A building’s use and construction can change how it responds to the same hazard, while its value sets the possible financial scale.
Policy terms determine how much of physical damage falls within coverage. A deductible is the amount retained before coverage responds, while a limit caps the insurer’s payment.
We can compare matching limits and deductibles when checking insurance terms. Check that policy limits and deductibles reflect the coverage terms currently in force.
How Does Catastrophic Risk Insurance Modeling Work?
A model turns asset records into a loss estimate through four connected calculations, from a possible event to its financial effect. Each calculation adds a different part of the catastrophe modeling process.
An early error can flow through every later calculation. We can follow one hypothetical flood affecting a business property to see how the linked steps work.
The event module builds possible scenarios
The event module creates possible flood scenarios with different strengths, locations, and likelihoods. One scenario might send deep water toward a business district, while another affects a smaller area.
The event catalog holds these possible events for analysis. Each event gives the model a defined starting point, rather than a prediction that a particular flood will occur.
For the example, the catalog includes a flood that reaches the business property. Its location and strength determine where the next calculation estimates water conditions.
The hazard module estimates physical intensity
The hazard module estimates the physical intensity of the flood at the property. It may describe water depth or other features of the event that affect buildings.
Hazard intensity is not the same as damage. Two properties can face similar water depth yet suffer different damage because their structures and uses differ.
An inaccurate address could place the business in the wrong part of the flood footprint. That mistake would alter the estimated intensity before damage is calculated.
The vulnerability module translates intensity into damage
The vulnerability module connects hazard intensity with expected physical damage. A vulnerability function describes how damage may change as flood conditions become more severe.
For the example, the function estimates damage to the business property at the flood depth assigned by the hazard calculation. The model uses its vulnerability assumptions to turn water conditions into a damage estimate.
That estimate remains distinct from monetary loss. It describes physical damage before the model applies insurance terms or other financial rules.
The financial module calculates monetary loss
The financial module applies coverage terms to physical damage to estimate monetary loss. It uses the policy’s deductible and limit to calculate the amount covered and the amount retained.
If the flood causes damage below the deductible, the policy may not pay for that loss. If damage exceeds the limit, the covered payment stops at that limit.
For example, the model may estimate flood damage first, then apply the business’s terms to calculate its insured loss. A different limit or deductible can change that financial result without changing the physical hazard.
Catastrophe models link these calculations, so the final number reflects choices made at several stages. An incorrect address, value, or coverage term can affect the path from scenario to result.
Teams should distinguish a modeled physical-damage estimate from an insured-loss estimate. The first concerns harm to property; the second also reflects the policy terms used in the calculation.
Read the final loss as the outcome of both the simulated hazard and the coverage terms applied to it.
How Do Event Catalogs Represent Rare Disasters?
A short claims record cannot show every rare event that could affect a portfolio. An event catalog is a simulated collection of possible catastrophe events used to estimate how often losses of different sizes could occur.
Simulated years are a modeling device, not a calendar forecast. Catastrophe models commonly use catalogs that cover tens of thousands of simulated years.
A deterministic model estimates loss for one specified scenario, such as a named earthquake with a chosen location and strength. It answers a focused question about that event.
A probabilistic model uses a catalog of possible events. It compares many scenarios and estimates how often losses of different sizes could occur across the simulated set.
The distinction matters when claims history is short. A rare disaster may not appear in the record, even though it could cause major losses across a portfolio.
A long catalog lets analysts explore events that did not happen during the years covered by claims. It does not say which event will happen next or when it will happen.
Simulated years are not extra years added to a real calendar. They are a way to represent possible event combinations and their chances within the model.
We can use a deterministic scenario to test one specific event, such as a large earthquake near a city. A probabilistic catalog instead shows a broader range of outcomes.
The two approaches answer different questions, so one cannot replace the other in every analysis. Use a deterministic scenario to examine a named event and a probabilistic catalog to compare a range of possible outcomes.
What Do AAL and PML Tell Us About Loss?
AAL summarizes the average loss across the simulated years, while PML focuses attention on a severe loss level. These loss measures answer different questions about catastrophe risk.
AAL is a long-run mean annual loss, not a promise of the loss in any single year. A 1-in-100-year PML represents a 1% annual chance of losses at or above that level.
| Measure | What it summarizes | How to read it |
|---|---|---|
| AAL | Long-run mean annual loss | Average across the model’s simulation catalog |
| PML | Loss at a selected severe level | Read with its probability or return label |
| Annual loss distribution | Possible loss amounts by chance | Shows a range, not one average |
AAL can help compare average loss across portfolios or scenarios. It may hide the difference between frequent small losses and rare, severe ones.
PML highlights a threshold that may matter when an organization considers its ability to absorb a large shock. The probability attached to that threshold gives it useful context.
A 1-in-100-year label does not mean an event arrives on a fixed 100-year schedule. It means the modeled loss level has a 1% chance of being met or exceeded in each year.
That annual chance can apply in two years in a row, or not occur for many years. It is not a timetable for the next event.
An annual loss distribution adds context by showing a range of possible outcomes rather than one number. The AAL and PML measures should be read with their definitions and assumptions in mind.
For insurers and other organizations, the useful metric depends on the question being asked. Compare each metric with the organization’s tolerance for frequent losses and rare financial shocks.
What Do Exceedance Probability Curves Show?
A portfolio can exceed a loss threshold through one major event or through several events whose losses add up. Exceedance probability curves show the chance of crossing a chosen loss amount in different ways.
OEP focuses on one event; AEP focuses on the total for the year. Both curves depend on the event catalog and on how the model defines loss.
OEP tracks the largest single-event loss
Occurrence exceedance probability, or OEP, shows the chance that any single event in a year exceeds a specified loss. It focuses on the largest single-event loss.
Imagine a portfolio with several coastal properties. One severe storm could cause a large loss across many sites, and the OEP curve tracks the chance of that event-level total passing a threshold.
OEP can help answer questions about a single event’s impact. It does not add losses from separate events together for the year.
AEP tracks total annual loss
Aggregate exceedance probability, or AEP, shows the chance that total losses from all events in a year exceed a specified amount. It adds together the losses from separate events.
Suppose the portfolio has three smaller events in the same year. None may exceed the threshold alone, yet their combined loss could cross it.
The AEP curve captures that annual sum, while OEP captures a single event’s loss. The curve chosen should match the question about the portfolio.
Both measures depend on the event catalog and the loss definition used. A curve for insured loss may not match one for total physical damage.
Curves also depend on the set of assets and financial terms represented in the analysis. If those change, the results may change too.
We should check the decision before reading a curve as a complete picture. Check whether a decision is about one event or the full year before selecting a curve.
How Do Models Show Risk Across a Portfolio?
Two properties can have moderate location-level hazard and still create a concentrated portfolio loss if the same event affects both. Portfolio analysis adds event and financial context that a location map alone cannot provide.
A hazard map shows local hazard, but it does not by itself estimate portfolio loss. Catastrophe models can connect the impact of one event across separate locations.
Consider a portfolio with one coastal property and one inland property. A hazard map may show different local threats at each site, but it may not show whether one event affects both.
A model can represent an event footprint that reaches several properties. It can also estimate how much loss those affected sites produce together.
Geographic correlation matters because nearby assets may face the same event at once. In a broad storm, a coastal location and an inland site can both suffer losses from different parts of the same system.
Reviewing each property in isolation can miss that concentration. The combined loss may be more important to the portfolio than either site’s local hazard rating.
Hazard maps remain useful for visualizing local intensity and identifying areas of concern. They provide a clear view of where a hazard may occur, but not the full financial result.
A catastrophe model adds event footprints, the exposure affected, and financial loss estimates. Teams can use property risk assessment methods alongside these outputs to understand site-level factors.
Map views and financial results each answer a different question. Pair location maps with event-based financial results when evaluating geographic concentration.
How Do Insurers Use Model Results in Underwriting?
An underwriter can use modeled loss to decide whether a property fits the insurer’s appetite at the proposed terms. Underwriting uses catastrophe models to support both individual risk choices and portfolio management.
Model results inform a premium, but they do not set it on their own. Insurers also consider the coverage offered and their broader approach to risk.
Underwriting sets acceptable exposure
At the policy level, an underwriter reviews whether a property’s likely loss fits the insurer’s appetite. This can involve a single location and the proposed coverage terms.
Across a book of business, insurers look for accumulation by peril and region. Many individually acceptable properties can still create a large combined exposure when one event affects them together.
A practical underwriting checklist can keep the review focused:
- Review the property’s location and construction.
- Compare modeled loss with the insurer’s risk appetite.
- Consider the proposed deductibles and limits.
- Monitor concentration by peril and region.
These checks help separate a property-level choice from a portfolio-level concern. An individual risk may fit on its own while adding too much concentration to one region.
Pricing reflects modeled loss and coverage
Pricing an individual risk considers modeled loss in light of its coverage. A policy with different limits or deductibles can create a different insured loss, even when the property stays the same.
Managing accumulation across a book asks a separate question: how much could the insurer lose if an event affects many policies? Catastrophe models help insurers compare those possible losses.
The American Academy of Actuaries’ catastrophe modeling paper discusses uses such as ratemaking, risk selection, mitigation, and reinsurance.
Model outputs are one input among several, not a fixed price rule. Record the reason for any exception so portfolio decisions remain consistent and reviewable.
How Do Reinsurance and Cat Bonds Use Catastrophe Models?
An insurer can use modeled loss scenarios to judge how much catastrophe exposure to retain and how much to transfer. Reinsurance and catastrophe bonds offer ways to shift defined financial risk.
Contract terms and model assumptions affect whether a modeled loss aligns with a recovery. A loss estimate alone does not show what a contract will pay.
Reinsurers use catastrophe models to assess and price catastrophe exposures. An insurer can compare modeled losses with the protection offered by a reinsurance agreement.
That comparison helps the insurer consider which losses it may retain and which it aims to transfer. The model gives a view of possible outcomes, while the agreement defines the actual protection.
A catastrophe bond, often called a cat bond, is a financial instrument that transfers defined catastrophe risk to capital-market investors. Investors take on specified risk under the bond’s terms.
Arrangers and investors use modeled loss distributions to support bond pricing and structure. The model helps describe possible losses that could affect the bond.
Contract triggers matter because they determine when a transfer responds. A model’s event definition may not match the contract’s trigger or terms exactly.
For example, the model may estimate damage across a region, while the contract may define risk through a particular event measure. Such differences can affect whether modeled losses align with recoveries.
We should separate the estimated risk from the legal terms that govern payment. Compare modeled event definitions with the actual contract language before treating a transfer as protection.
How Can Banks and Public Agencies Use Catastrophe Models?
A bank may have a geographically concentrated loan book even when it does not insure the properties behind those loans. Catastrophe models can help banks and public agencies assess physical risk beyond insurance portfolios.
An asset-level estimate is not the same as an institution-wide financial assessment. A building’s modeled damage can inform a wider review of loans, services, and public needs.
Banks assess physical risk in financial portfolios
Banks can review physical risk tied to real estate, infrastructure, agriculture, and lending. A hazard that affects a borrower’s property may also affect repayment or business activity.
That does not mean a location-level loss estimate directly measures the bank’s total credit exposure. The institution must consider its broader financial links to affected assets and borrowers.
Public agencies plan for disaster impacts
Public agencies can use modeled risks to plan for disaster response and preparedness. Their work also needs to consider uninsured damage, which may affect residents and services without appearing in insured-loss totals.
Four applications can help frame the analysis:
- Review bank credit exposure across a loan book.
- Screen infrastructure investments for physical risk.
- Prepare public disaster plans and response resources.
- Prioritize resilience projects across exposed communities.
A public agency might compare likely damage to roads, public buildings, or other services. That view can support planning for disruptions that affect a wider area.
Institutions can also compare risks across different regions and asset types. A single asset estimate remains useful, but it cannot replace an institution-wide view.
Models help connect possible physical impacts with the people and organizations that rely on affected assets. Map the financial exposure to places where a disaster could interrupt assets, borrowers, or public services.
How Should Climate Change Shape Model Assumptions?
Historical claims remain useful, but they may not represent future hazard conditions or where people and assets will be located. Climate risk and exposure growth can make past losses an incomplete guide.
Inflation adjustment helps compare costs over time, but it does not capture every social or ecological loss. Climate Central’s U.S. billion-dollar disaster dataset tracks events from 1980 onward.
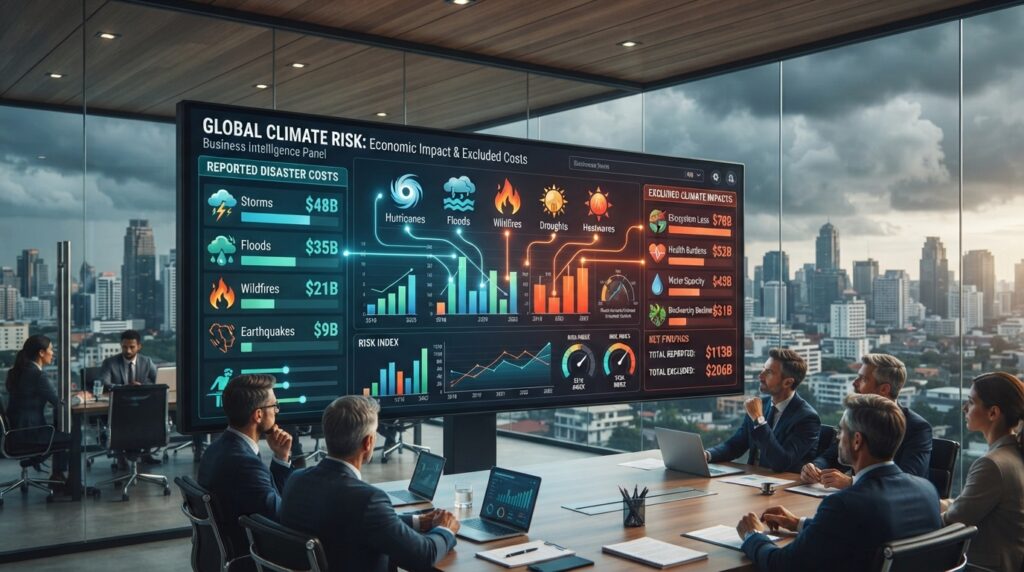
Climate Central took stewardship of the dataset in 2025, after NOAA maintained it from 1980 through the 2025 transition. The estimates adjust costs to 2026 dollars using the U.S. Bureau of Labor Statistics Consumer Price Index.
| Cost category | Counted in dataset | Examples |
|---|---|---|
| Direct physical damage | Yes | Buildings, contents, vehicles, public, agricultural, and infrastructure assets |
| Business interruption and wildfire suppression | Yes | Business interruption; wildfire suppression costs |
| Environmental, health, and supply-chain effects | No | Natural-capital loss, health-care costs, supply-chain interruption |
The total direct costs include insured and uninsured damage to buildings, contents, vehicles, public assets, agriculture, and infrastructure. They also include business interruption and wildfire suppression.
The estimates exclude natural-capital losses, environmental degradation, health-care costs, the statistical value of life, and supply-chain or contingent business interruption costs. A total therefore reflects defined categories, not every effect of a disaster.
Forward-looking climate scenarios, including IPCC pathways, can supplement historical experience. Scenario analysis helps teams explore possible future conditions, not predict a specific event on a set date.
Changing exposure also matters: people, buildings, and businesses may move or grow in places with different hazards. The dataset’s cost categories help show what its totals include.
Historical data remains useful when interpreted with its scope in mind. State clearly which loss categories a dataset measures before comparing its total with a model output.
What Creates Uncertainty in Catastrophe Modeling?
Two credible models can produce different loss estimates for the same portfolio because their assumptions and data are not identical. Uncertainty can enter through event frequency, hazard intensity, exposure records, vulnerability functions, and financial terms.
Compare assumptions before comparing headline loss figures. Differences do not automatically mean that one model is wrong.
Uncertainty in the event and hazard assumptions
Aleatory uncertainty describes the natural variation in events. The next storm can differ from the last one in strength, path, and the places it affects.
Epistemic uncertainty reflects limits in knowledge or model assumptions. Analysts may not have full information about how often a hazard occurs or how intensely it reaches each location.
Different catastrophe models can represent events and hazards in different ways. Those choices can produce different loss estimates, even when the models assess the same portfolio.
Uncertainty in exposure, vulnerability, and financial terms
Exposure records and building details also affect results. If a property address is slightly wrong, a model may place it in a different part of a hazard area.
Suppose one record lists a building’s construction accurately, while another gives only a broad building type. The models may estimate different damage under the same event because they have different information.
Financial terms create another difference. A change in a policy limit or deductible can alter insured loss without changing the hazard or physical damage estimate.
When two outputs differ, we should first compare their event catalogs, hazard assumptions, exposure data, and loss definitions. That check helps explain the gap before anyone treats one number as the answer.
A result may be more useful as a range than as a single point estimate. Treat a result as a range of plausible outcomes when the inputs or assumptions are uncertain.
How Can Teams Validate and Govern Model Results?
A useful model result is one that an organization can trace back to its data, assumptions, and decision process. Governance gives teams a repeatable way to check how results were made and used.
Preserve the input snapshot and model settings used for each material decision. That record lets reviewers understand the basis for a result later.
A five-part governance checklist can make review practical:
- Document the model version and its assumptions.
- Validate geocoding against the location records.
- Reconcile exposure records with policy terms.
- Compare outputs with historical experience and scenarios.
- Record review and approval for material decisions.
A model version matters because settings and representations can change. A team should be able to identify which version produced the result it used.
Geocoding checks help confirm that locations sit in the right places. Reconciliation also connects the exposure records to the policy terms used for the analysis.
Historical experience and scenario comparisons can help teams review whether outputs make sense for their purpose. They should document the reason when an output differs from other evidence.
The Oasis Loss Modelling Framework is an open-source catastrophe modeling platform. ACORD works on standards for collecting and sharing exposure data.
Open frameworks and shared standards can aid transparency, but they do not replace an organization’s own checks. Keep the input snapshot and settings tied to each material decision.
What Is Changing in the U.S. Catastrophe Insurance Market?
U.S. property catastrophe renewals moved lower during 2026, while policy and disaster indicators capture different parts of the insurance environment. Market signals do not measure physical risk in the same way as catastrophe models.
The rate-on-line index is not risk-adjusted, so it is not a pure measure of changing hazard. It tracks dollars paid for coverage on a consistent program base year over year.
Renewal pricing reflects recent market movement
At the January 1, 2026 renewals, the Guy Carpenter U.S. Property Catastrophe Rate on Line Index fell 12%. After the June and July renewals, it was down 16% for 2026 to date.
| Market indicator | Period | Value | What it measures |
|---|---|---|---|
| January 1 renewal change | 2026 renewals | Down 12% | Year-over-year dollars paid on a consistent program base |
| June and July renewal year-to-date change | 2026 to date | Down 16% | Year-to-date change in the same index |
| NOAA disaster count | 2023 and 2024 | 28 and 27 | U.S. billion-dollar disasters in each year |
The rate-on-line index measures year-over-year changes in dollars paid for coverage on a consistent program base. It is not adjusted for changes in risk.
That means a lower index does not prove that physical hazard or modeled loss fell by the same amount. The 2026 renewal index changes describe market pricing, not a direct hazard measure.
Disaster data and state reforms shape the context
NOAA logged 28 U.S. billion-dollar disasters in 2023 and 27 in 2024. These counts describe observed disasters that crossed a cost threshold, not the full range of future modeled events.
At least 18 U.S. states had introduced 2026 legislation to reform insurance programs for disaster preparedness and consumer protection. Those proposals provide policy context, but they do not prove reforms have already changed coverage.
Keep market pricing, observed disaster counts, and modeled future losses as separate indicators when interpreting risk.
Teams should note the period and meaning of each indicator before comparing it with another. A price index, disaster count, and modeled loss answer different questions.
Conclusion
Catastrophe models make complex risk easier to compare when we understand what their estimates include and what they leave out. Useful decisions combine fit-for-purpose data, clear assumptions, and the right loss measure.
We can start by listing the assets that matter most and the decisions a model should inform. That keeps the analysis tied to real needs rather than a number without context.
Start by checking the location, value, and coverage terms for the assets most important to your organization.